← Blog
/

Data annotation vs data labeling: What you need to know in 2026
Toloka Arena is live. See how your model ranks.
Hybrid data generation blends scale and quality for better training
Updated September 2026
Data annotation and data labeling are often used interchangeably, and in casual conversation that is fine. But the distinction matters when you are designing a data pipeline, hiring annotators, or deciding how much quality control a project needs. In short: data labeling is a subset of data annotation. Labeling assigns a predefined tag to a data point. Annotation is the broader category that includes labeling, spatial markup, entity tagging, preference ranking, and any other structured metadata added to raw data.
That distinction has grown more consequential since 2023. The annotation work behind LLM training now includes tasks that do not look like traditional labeling at all: writing instruction–response pairs for supervised fine-tuning, ranking model outputs for RLHF and DPO, evaluating multi-turn conversations for safety, and red-teaming models to find harmful outputs. These are all data annotation tasks, but calling them "labeling" would undersell the complexity and the expertise they require.
This guide clarifies the difference between data annotation and data labeling, covers both traditional and LLM-era use cases, and explains how the choice between them shapes cost, quality, and model performance.
What is data annotation?
Data annotation is the process of adding structured, meaningful metadata to raw data so that machine learning models can learn from it. The raw data can be images, text, video, audio, 3D point clouds, or any other format a model needs to process. The metadata can be as simple as a class label or as complex as a multi-dimensional rubric applied to a model's conversational output.
In supervised learning, annotation is what creates the ground truth. The model learns by mapping inputs to the labels, tags, bounding boxes, or rankings that human annotators have provided. The quality of that ground truth directly determines the ceiling of what the model can learn. Poor annotation does not just reduce accuracy; it introduces systematic errors the model will reproduce at scale.

Data annotation tasks include image, text, video, and audio analysis. Source: Toloka.ai
In 2026, the scope of data annotation extends well beyond traditional computer vision and NLP tasks. Teams building large language models need annotation for instruction tuning, preference alignment, safety evaluation, and domain adaptation. Teams building multimodal models need annotation that connects visual, textual, and audio information within the same example. The common thread is that all of these require human judgment applied to raw data in a structured way.
What is data labeling?
Data labeling is the most common and simplest form of data annotation. It involves assigning a predefined tag or category to each data point: this image contains a cat, this email is spam, this review is positive, this transaction is fraudulent.
The defining characteristic of labeling is that the output is a discrete tag from a fixed set. There is no spatial information, no ranking, no free-text description, just a category assignment. That constraint makes labeling faster, cheaper, and easier to scale. It also means labeling is sufficient for many production tasks, particularly binary classification, multi-class classification, content moderation, and basic filtering.
For a deeper look at how data labeling works in practice and when it makes sense to outsource it, see our guide to what data labeling is and how it works.
Key differences between data annotation and data labeling
The practical difference comes down to output complexity. Labeling produces a tag. Annotation produces structured information that can include tags, spatial coordinates, temporal references, entity relations, rankings, or free-text judgments. The table below summarises the key distinctions:
Dimension | Data labeling | Data annotation |
Scope | Assigning predefined tags or categories to data points | Adding any structured metadata: labels, spatial markup, relations, rankings, free-text descriptions |
Typical output | Class label, binary tag, sentiment score | Bounding boxes, segmentation masks, entity spans, preference rankings, instruction–response pairs |
Complexity | Lower. Well-defined categories, minimal ambiguity | Higher. Multi-dimensional, context-dependent, often requires domain expertise |
Scalability | Highly scalable. Can be crowdsourced or automated | Varies. Simple annotation scales well; preference ranking and expert evaluation scale harder |
Quality control | Agreement metrics, gold-standard checks | All of the above plus rubric calibration, LLM-based QA, expert adjudication for complex tasks |
2026 relevance | Still essential for classification, moderation, content filtering at scale | Expanding rapidly into LLM training: SFT data, RLHF preference data, safety evaluation, agent benchmarks |

Image data annotation tasks on the Toloka platform encompass both binary images classification and object location. Source: TheSequence
One way to think about this: every labeling task is an annotation task, but not every annotation task is a labeling task. When someone says "we need to label our data," they might mean simple classification, or they might mean the full range of annotation work a project requires. Clarifying which one up front prevents mismatched expectations about cost, timeline, and annotator expertise.
The annotation complexity ladder
One reason the labeling-vs-annotation distinction matters is that annotation tasks exist on a spectrum of complexity. Each level requires different tooling, different annotator expertise, and different quality control. The work that goes into labeling an image for classification is fundamentally different from the work that goes into ranking two LLM outputs for RLHF.
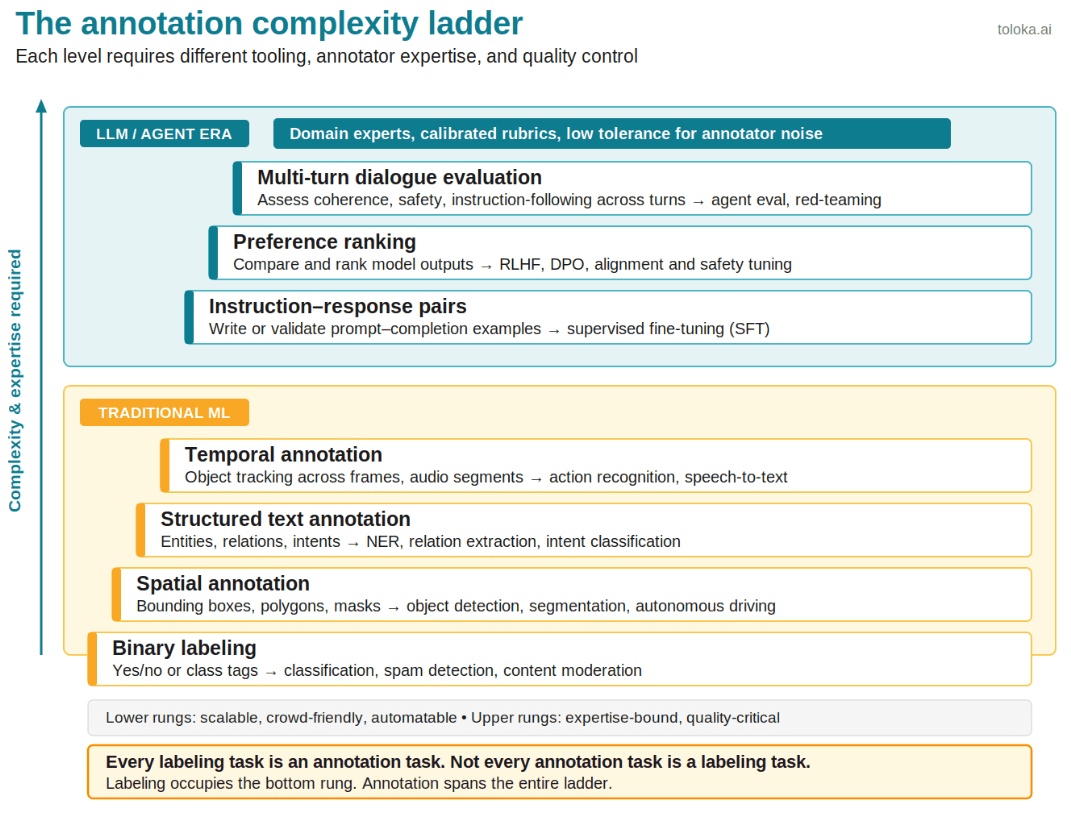
The annotation complexity ladder: each rung demands different tooling, expertise, and QA. Source: Toloka.ai
Annotation complexity | What annotators do | Model task it enables | Quality requirements |
Binary labeling | Assign yes/no or class tags to data points | Classification, spam detection, content moderation | Clear guidelines, inter-annotator agreement |
Spatial annotation | Draw bounding boxes, polygons, segmentation masks | Object detection, instance segmentation, autonomous driving | Pixel-level accuracy, consistent boundary rules |
Structured text annotation | Tag entities, relations, intents within text | NER, relation extraction, intent classification | Schema consistency, edge-case coverage |
Temporal annotation | Track objects across video frames, label audio segments | Object tracking, action recognition, speech-to-text | Frame-to-frame continuity, interpolation QA |
Instruction–response pairs | Write or validate prompt–completion examples for SFT | Instruction-tuned LLMs, chatbots, coding assistants | Domain expertise, format consistency, factual accuracy |
Preference ranking | Compare and rank model outputs for RLHF/DPO | Alignment, safety, helpfulness optimisation | Rubric calibration, trained raters, low noise tolerance |
Multi-turn dialogue evaluation | Assess coherence, safety, and instruction-following across conversation turns | Conversational AI, agent evaluation, red-teaming | Expert raters, structured rubrics, context tracking |
The lower levels (binary labeling, spatial annotation) are well-understood and highly scalable. The upper levels (preference ranking, dialogue evaluation) are newer, harder to scale, and more sensitive to annotator quality. As Nathan Lambert's RLHF Book notes, as of 2026 there are still no open models with fully open human preference data released alongside the methods used to collect it. Preference annotation remains one of the most opaque and most critical pieces of the LLM pipeline.
Train your AI with expert human data Toloka Platform delivers high-quality annotation data for LLMs, computer vision, and NLP. Domain experts, AI-assisted QA, pay-as-you-go. |
Data annotation and labeling in traditional ML
Before the LLM era, most annotation work fell into three domains: computer vision, natural language processing, and speech recognition. These use cases remain important and account for the majority of annotation volume worldwide.
Computer vision
Image classification uses labeling: assign a category to each image. Object detection, instance segmentation, and semantic segmentation require spatial annotation: bounding boxes, polygons, or pixel-level masks that encode where objects are, not just what they are. Autonomous vehicle pipelines combine both, often across LiDAR, camera, and radar modalities simultaneously. For a detailed comparison of image annotation tools, see our guide.

A typical semantic segmentation task presumes outlining object shapes in an image. Source: Toloka.ai

A self-driving car's view of the world with bounding boxes around objects is based on manually annotated images. Source: NVIDIA Drive
Natural language processing
Sentiment analysis is a labeling task: positive, negative, neutral. Named entity recognition (NER) is an annotation task: identifying and categorising entities within text. Intent classification, relation extraction, and coreference resolution all require structured annotation beyond simple tags. For text annotation workflows, the quality of the annotation schema matters as much as the quality of individual labels.

Toloka's adaptive ML models combine automated and manual labeling for social media monitoring. Source: Toloka.ai
Speech and audio
Transcription is a labeling task when it maps audio segments to text. Phoneme annotation, speaker diarisation, and emotion tagging are annotation tasks that add structured metadata beyond the transcript. Audio data labeling at scale requires clear guidelines and consistent annotator calibration, because subjective audio features like emotion or intent introduce higher disagreement rates than visual tasks.
How annotation has changed for LLM training
The most significant shift in data annotation since 2023 is the expansion from labeling existing data to creating new training examples and evaluating model behaviour. Traditional annotation asks "what is in this data?" LLM annotation asks "how should a model respond?" and "which response is better?" These are fundamentally different tasks.
Instruction–response pairs for supervised fine-tuning
Supervised fine-tuning (SFT) requires annotators to write or validate prompt–completion pairs that define how a model should behave. Unlike traditional labeling, there is no pre-existing "correct answer" to select from. The annotator must produce one, often requiring domain expertise, and the result must be consistent in style, format, and reasoning across thousands of examples.
Preference data for RLHF and DPO
Preference annotation involves comparing two or more model outputs and ranking them by quality. This is the core data type for RLHF and direct preference optimisation. The quality bar is exceptionally high: research shows that noise in preference annotations commonly exceeds 20% in real datasets, and this noise directly degrades alignment performance.
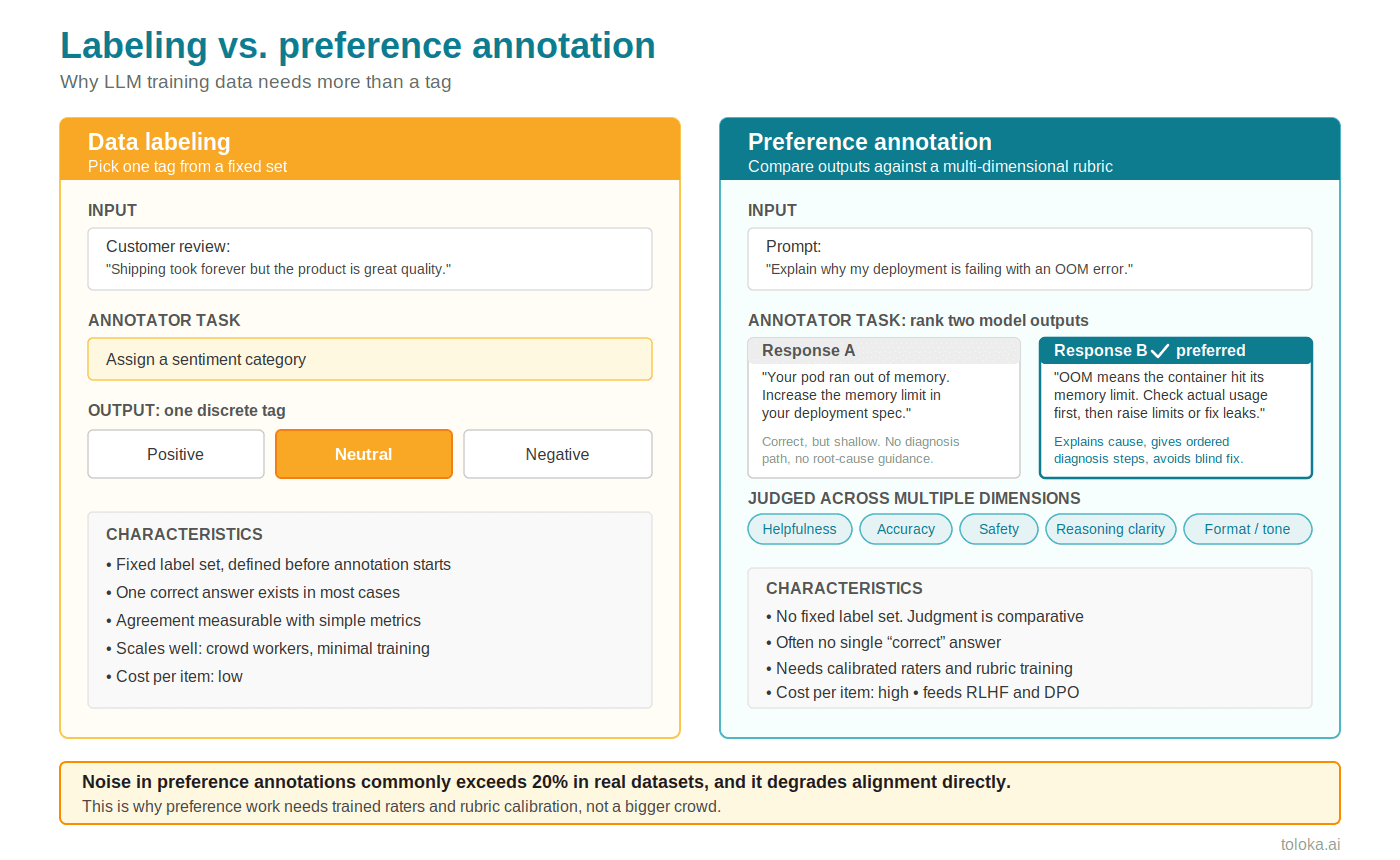
Labeling picks one tag from a fixed set. Preference annotation is a comparative judgment across several quality dimensions. Source: Toloka.ai
Preference annotation is not labeling. There is no fixed set of tags. The annotator must apply a multi-dimensional rubric covering helpfulness, accuracy, safety, tone, and formatting, then make a comparative judgment. This requires trained raters with calibrated standards, not crowd workers choosing between binary options.
Safety evaluation and red-teaming
Evaluating models for harmful outputs, bias, and failure modes is an annotation task that sits at the top of the complexity ladder. Red-teaming involves deliberately probing a model for unsafe behaviour and documenting the results. Safety evaluation requires annotators to assess whether a model's response violates specific policy constraints. Both feed back into AI safety and alignment processes.
Agent and multi-turn evaluation
As AI agents become more capable, evaluation requires annotators to assess entire interaction sequences, not just individual outputs. Did the agent follow instructions across turns? Did it maintain context? Did it escalate appropriately? This kind of annotation requires structured rubrics, expert raters, and tooling that supports multi-turn review.
Why annotation quality matters more than annotation volume
A persistent mistake in data annotation projects is treating volume as the primary goal. For traditional labeling tasks with clear categories and low ambiguity, scale is indeed the main lever. But for the annotation tasks that matter most in 2026, specifically SFT data, preference rankings, and evaluation sets, quality dominates.
Research consistently shows that a few thousand high-quality, task-aligned examples outperform much larger noisy datasets for LLM fine-tuning. The same applies to preference data: inconsistent rankings introduce conflicting training signals that make the model's behaviour less predictable, not more aligned.
Effective quality control for annotation in 2026 includes inter-annotator agreement metrics for labeling tasks, rubric calibration sessions before preference annotation begins, LLM-based inline QA that catches errors during annotation rather than after, expert adjudication for disagreements in high-stakes tasks, and held-out evaluation sets that test whether the annotated data actually improves model behaviour.
How to choose the right approach for your project
The choice between labeling and broader annotation depends on three factors: the model task, the required output complexity, and the quality standard.
Use labeling when the task has clear categories, low ambiguity, and high volume requirements. Image classification, content moderation, spam filtering, and binary sentiment analysis are all strong candidates. Labeling scales well with automated data labeling and crowd-based approaches.
Use annotation when the task requires spatial information, entity relations, temporal tracking, preference judgments, or expert reasoning. Object detection, NER, video annotation, SFT data creation, and RLHF preference ranking all require annotation beyond simple tags.
Use both when the project has multiple data needs. A typical LLM development pipeline uses labeling for content filtering and moderation, spatial annotation for multimodal training data, instruction-response annotation for fine-tuning, and preference annotation for alignment. Different stages require different annotator profiles, tools, and QA processes.
How Toloka supports data annotation at scale
Toloka structures its annotation platform around the complexity ladder. General annotators handle high-volume labeling and classification tasks. AI tutors work on instruction–response pairs and intermediate annotation. Domain experts across 90+ specialties handle preference ranking, safety evaluation, and tasks that require specific professional knowledge. Built-in LLM-based QA runs inline during annotation, and AI-assisted project setup helps translate requirements directly into task configuration.
Build your annotation pipeline From image labeling to RLHF preference data, Toloka Platform adapts to your annotation needs with expert annotators and built-in QA. |
Frequently asked questions
" height="28px" id="v_HNFUCmW" transform="translate(10 10)" width="28px"/></svg>)
What is the difference between data annotation and data labeling?
Data labeling is a subset of data annotation. Labeling assigns a predefined tag or category to a data point (such as "spam" or "not spam"). Annotation is the broader category that includes labeling plus any other structured metadata: bounding boxes, segmentation masks, entity tags, preference rankings, instruction–response pairs, and free-text evaluations.
What is data annotation in machine learning?
Data annotation in machine learning is the process of adding structured metadata to raw data so that models can learn from it. In supervised learning, annotation creates the ground truth that the model maps inputs to. The quality of annotation directly determines the ceiling of model performance.
What are examples of data annotation?
Examples range from simple to complex: tagging an image as "cat" or "dog" (labeling), drawing bounding boxes around pedestrians for autonomous driving (spatial annotation), marking named entities in text (NER annotation), writing instruction–response pairs for LLM fine-tuning (SFT annotation), and ranking model outputs by helpfulness for RLHF (preference annotation).
Why does data annotation matter for LLMs?
LLMs require annotation at multiple stages of development. Supervised fine-tuning needs instruction–response pairs that define model behaviour. RLHF and DPO need preference rankings that align model outputs with human values. Safety evaluation needs structured assessments of model responses. Without high-quality annotation at each stage, the model's behaviour becomes unpredictable and potentially harmful.
What is the difference between data labeling and data annotation for AI?
For AI specifically, the distinction matters because modern AI systems need both. Labeling handles the high-volume, clear-category tasks like classification and filtering. Annotation handles the complex, judgment-intensive tasks like preference ranking, entity annotation, and evaluation. Teams that treat all data preparation as "labeling" tend to underestimate the expertise and quality control required for the annotation-heavy stages.
How much does data annotation cost?
Costs vary enormously by complexity. Simple binary labeling can be done at scale with crowd workers at low per-label costs. Preference annotation for RLHF requires trained raters with calibrated rubrics and costs significantly more per example. Domain-expert annotation for medical, legal, or financial tasks is the most expensive per unit but often delivers the highest impact per example. The most accurate cost model accounts for quality, rework rates, and the cost of errors that reach training, not just the per-label price.
Related reading
What is data labeling in machine learning and how it works
Data labeling methods for machine learning
Image annotation tools: How to label data that actually teaches AI
Supervised fine-tuning: How SFT shapes LLM behaviour
RLHF: Training AI with human feedback
Automated data labeling with ML
Labelled data vs. unlabelled data
Subscribe to our newsletter
Product updates, case studies and the latest news from our team, straight to your inbox